```{r setup, include=FALSE} tutorial_name <- tools::file_path_sans_ext(knitr::current_input()) repo_root <- dirname(dirname(dirname(knitr::current_input(dir = TRUE)))) knitr::opts_knit$set(root.dir = repo_root, base.url = "/") knitr::opts_chunk$set( fig.path = paste0("images/tutorials/", tutorial_name, "/"), fig.width = 8, fig.height = 5, dev = "svg" ) ``` ## Introduction ### Overview In this tutorial, we will use cutting-edge fossil-phylogenetic methods to estimate trees with oriented (i.e. budding) speciation nodes. These trees also explicitly accommodate stratigraphic ranges (the time between first and last occurrence of a species), allowing for a more taxonomic approach that better matches the assumptions of the fossil record. In particular, we will use the stratigraphic-range fossilized birth-death model (SRFBD) (@stadler2018fbdr, @stolz2025srfbd), which expands on the FBD model (@stadler2010fbd, @heath2014fbd) to allow for stratigraphic ranges and budding speciation. This model is most appropriate for groups with a dense fossil record with multiple specimens per species. To illustrate its benefits, we will be using the Canidae dataset first published by @slater2015canids, later complemented with some extra data for a test of the SRFBD implementation in @stolz2025srfbd. This dataset contains 116 extinct and 5 extant canid species, including stratigraphic ranges (times of first and last fossil occurrence), and morphological characters (123 characters, including 2, 3, 4, and 5 state characters). We will then use R to analyze the results of the SRFBD analysis, and gain some insight on what budding phylogenetic trees can tell us about the evolutionary history of canids. #### Software prerequisites - [BEAST2](https://beast2.org) is the only software for which the SRFBD model is currently implemented. Make sure to download all the auxiliary programs, specifically BEAUti, TreeAnnotator, LogCombiner, and Tracer. You will also need to install the `starbeast`, `BEASTlabs`, `SA`, and `feast` packages, either through BEAUti or package manager. - For details on installing BEAST2 in a cluster, see [this README](https://github.com/plewis/deploy/blob/main/README.md) (scroll down to the Setup for running on a cluster section). - [sRanges](https://github.com/jugne/stratigraphic-ranges) is the BEAST2 packages containing the SRFBD implementation. Follow the installation instructions on the README. Note that `v0.1.1` is currently broken, so install [v0.1.0](https://github.com/jugne/stratigraphic-ranges/releases/tag/v0.1.0). - To install on a cluster, simply extract the `zip` file for the respective release into the directory where you are keeping BEAST2 packages within your cluster, and rename the directory to `sRanges`. - [R](https://www.r-project.org/) will be used both for inference and post-processing. Since there is currently no BEAUti template for sRanges scripts, we will use the R scripts provided with this tutorial to build the .xml files. - R packages to download from CRAN (`install.packages("package_name")`): `ape`, `coda`, `devtools` - [paleobuddy](https://github.com/brpetrucci/paleobuddy) is my birth-death simulation package. It is currently the only package with tools for reading and manipulating budding phylogenetic trees. The latest version is not on CRAN, so make sure to install it from the `development` branch with `devtools` (`install_github("brpetrucci/paleobuddy@development")`).
### Getting Started If you'd prefer to follow this tutorial through an R markdown file, download it here: [srfbd.Rmd](/files/tutorials/srfbd/srfbd.Rmd){: .btn .btn--primary download="srfbd.Rmd"} Once you've installed the required software and downloaded all the files above, let's start setting up our analyses. First, make sure to add all the files to some directory--that will be our working directory. I like to organize things into `data`, `scripts`, and `output` directories, but feel free to organize it differently if it makes more sense to you! For me, I have a directory within my website called `srfbd`, and within it I have a `data` directory with the morphological and range data files, and a `scripts` directory where we will be writing all of our BEAST2 scripts. The two `xml` template files and `R` script writing files provided with this tutorial are on the `srfbd` directory itself. Let's set up some useful directory variables! ```{r} # base directory, where your .xml and .R files are base_dir <- "/Users/petrucci/Documents/website/brpetrucci.github.io/files/tutorials/srfbd/" # scripts, data, and output directories scripts_dir <- paste0(base_dir, "scripts/") data_dir <- paste0(base_dir, "data/") out_dir <- paste0(base_dir, "output/") ``` We will use these directories to write our scripts, and then analyze the output later. Of course you could simply You also need to install and attach the packages discussed above. ```{r eval=FALSE} # install packages from CRAN install.packages(c("ape", "coda", "devtools")) # install the paleobuddy development branch pak::pak("brpetrucci/paleobuddy@development") ``` We can then attach them. ```{r message=FALSE} # attach packages library(ape) library(coda) library(paleobuddy) ``` We are now ready to start the tutorial proper! ## Inference ### Writing scripts First, let's write some BEAST2 scripts! Because there is currently no available BEAUti template for the SRFBD model, we must do some manual writing, which is challenging for `xml` files. The usual process would be writing a template with BEAUti for a traditional FBD analysis, then careful reading of a working SRFBD `xml` to apply all the required changes. It's a lengthy and error-prone process, especially if you're not used to the `xml` format. Lucky for you, I suffered so you don't need to! I wrote a few scripts to do the process for you. Here's a rundown: - `xml_writer.R` creates a ton of functions that write the script proper. It reads the user's preferences (laid out in `canidae_setup.R` or a file like it) and writes each part of the `xml` for a complete SRFBD analysis. It is certainly not encompassing of all the possible variation you could have in an SRFBD analysis, however--only the specifics I have needed for my analyses in the past. Please feel free to contact me for any help modifying this (and any other file in this tutorial) for your uses. - `canidae_setup.R` sets up the specifics we would like for the Canidae analysis, through writing one simple function: `scripts_setup()`. That function is where you would set your data, priors, and operators. It is currently set up for the simple morphological-only analysis we will use as an example in this tutorial, but `xml_writer.R` is perfectly able to handle DNA data as well, and all one would need to add molecular data into the mix is to create analogous priors, operators, and data blocks to the morphological ones here. Similarly, any modifications to the desired specifications (_e.g._, using a different morphological clock model) would be achievable by slightly changing (or adding/removing) the priors and operators. It is difficult to give a full rundown of these scripts in a short tutorial, but they have hopefully been commented enough for understanding. In the future I will add more setup scripts to show examples of how we might set up different analyses. - `header.xml` and `maps.xml` are simple templates needed for the `xml` file, that are too long to justify writing into an R string. Simply keep them in the same `base_dir` as the `R` files and you should not have to worry about them. #### The SRFBD model for joint inference of budding phylogenetic trees and divergence times A full description of the SRFBD model is outside of the scope of this tutorial, and for that I recommend the references listed in [Overview](#overview), and my Palaeoverse lecture on 27/08/2026 (link to the recording when we have it). For now, let's do a quick rundown of the model and its component parts. Our model has two main components: the tree prior (SRFBD), and the morphological evolution model (MkV, see @lewis2001mk). Both of these models allow us to calculate the probability of our **data** given the values of our **parameters** (*i.e.,* the likelihood), and we can then use the MCMC algorithm to estimate our posterior distribution (the probability distributions of our **parameters** given our **data**). - **SRFBD** models the construction of our phylogenetic tree proper using a birth-death-sampling model. - The data are the stratigraphic range of each canid species in our analysis. If you open the `canidae_ranges.tsv` file, you will see the times of first and last appearance for each species, including some uncertainty. - The parameters are the speciation (`lambda`, $\lambda$), extinction (`mu`, $\mu$), and fossil sampling (`psi`, $\psi$) rates, and the origin of the process (*i.e.,* the time of speciation of the first lineage in the tree). BEAST2 reparameterizes the rates into diversification ($\lambda - \mu$), turnover ($\frac{\mu}{\lambda}$), and sampling proportion ($\frac{\psi}{\mu+\psi}$), so these are the parameters for which we need priors and operators. We are using fairly standard priors for these, with hyperparameters chosen to represent our prior expectations of canid evolution. Each of these will be written as `parameterNameFBD.t:tree` in our scripts (*e.g.,* `diversificationRateFBD.t:tree`). - **MkV** models the evolution of the morphological characters within the underlying tree. - The data are the morphological characters scored for each species in our analysis. `canidae_morpho.nex` shows the value of each of our 123 characters for each of our 121 species. Here we have 2, 3, 4, and 5 state characters. We have no invariant characters, so we must apply a correction to the likelihood (hence the V in MkV). This is fairly simple in BEAST2, and already assumed by our setup scripts. Most available morphological matrices will exclude invariant characters. - The parameters for the MkV model depend on your desired clock model. Here, we are using an uncorrelated lognormal clock, meaning the clock (in simple terms, the speed of morphological transitions) in each branch will be an independent draw from the same lognormal distribution. We set a parameter for the standard deviation of that distribution (`ucldStdev.c:morpho`), and a parameter for the mean of drawn rates (`ucldMean.c:morpho`). For more details on the models available in BEAST2, check out their [tutorials](https://www.beast2.org/tutorials/). In short, for each generation of our MCMC, the model will attempt to move one of our parameters, or the underlying budding phylogeny, and accept or reject that move based on how it changes the posterior distribution. This allows us to jointly estimate our phylogeny (including speciation node orientation, which is only possible for this model currently!) and divergence times. What a time to be alive!
Now let's write some `xml` scripts! Here we need to consider a few questions about our MCMC setup, which I set as arguments for the `scripts_setup` function. - `n_scripts` describes how many scripts we would like to build with the exact same setup. Running multiple analyses for the same script is recommended so you can ensure your final posterior sample is not affected by the initial state. For your convenience, `xml_writer.R` automatically chooses new initial states (drawing each initial value from the corresponding prior) each time it writes a new script, so you just need to tell it how many scripts to write. I chose 4, but feel free to run more or less depending on the resources you have available. - `n_gens` describes how many generations we should run our MCMC for. I am using 1 billion generations, which is likely overkill for a morphological-only model. Again, feel free to change this value. BEAST2 makes it very easy to resume runs if you feel like it needs more generations, so don't feel stressed about this choice. - `log_every` describes how often we want the model to sample from the MCMC and store the current values of our parameters and tree in the corresponding `.log` and `.trees` files. I set it to 1 million, so that each run will end with 1000 posterior samples before burnin. - `store_every` describes how often BEAST2 should store the current value of parameters in a `.state` file, which can then be used to resume analyses. I recommend setting this to the same value as `log_every`, so as to avoid jumps in your posterior sample in case you need to resume an analysis. For more details on resuming an analysis, check out the [Resuming BEAST2 runs](#resuming) box below. - `attach` describes where in the stratigraphic range of each species to attach the morphological data. One might choose to attach the data at both the first and last occurrence (`"both"`), or just the first occurrence (`"first"`). It is unclear as of now which of the two approaches lead to more accurate estimates (I'm working on it!), but for the sake of example here we will just attach the data to the first occurrence. Now that we understand the arguments, we just need to source the setup scripts, set values for the arguments, and run the `scripts_setup` function! ```{r eval = FALSE} # source your setup script source(paste0(base_dir, "canidae_setup.R")) # xml_writer.R is already sourced by the setup script # number of scripts n_scripts <- 4 # number of generations n_gens <- 1000000000 # how often to sample the MCMC and store into .log and .trees files log_every <- 1000000 # how often to store the current state into .state file store_every <- 1000000 # which occurrence do we want to attach the morphological data to? attach <- "first" # write scripts scripts_setup(n_scripts, n_gens, attach, scripts_dir, log_every, store_every) ``` This will write scripts of the form `srfbd_first_N.xml` into the `scripts/` directory, where `N` goes from `1` to `n_scripts` (the `_N` is ommitted if you choose to set `n_scripts` to `1`). Feel free to alter the `script_name` variable in `canidae_setup.R` to change that convention. ### Running the Analysis Now that we have our scripts ready, let's run them! You can of course do all of the steps I will list below using the GUIs installed with BEAST2 in your local machine. This would take quite a bit of time though, so I will assume you are running these commands on a cluster, and will therefore list command line commands for them. First, we need to run our BEAST2 analyses proper. Again I will assume you have your scripts in the `scripts` directory, and a (currently empty) `output` directory in the same parent folder. For each script `script/script.xml`, we can run: ``` /path/to/beast/bin/beast scripts/script.xml ``` By default, the `beast` executable will be installed to the `bin` directory of the overarching `beast` installation folder. In my cluster, the first command reads `/home/petrucci/beast/bin/beast`, for example. Of course if you'd prefer you could add the `bin` directory to your PATH in order to be able to just use the `beast` command. If you build your scripts using my `canidae_setup.R` script as-is, this analysis will write your output files as `output/script.log` and `output/script.trees`. You may change this in the ` Resuming BEAST2 analyses
There are a number of reasons you might need to resume your BEAST2 analyses. Your cluster might have gone under maintenance and cancelled running jobs, or you might need to run the analysis longer for it to converge. Thankfully, BEAST2 makes it fairly easy to resume a run. As your analysis runs, BEAST2 will write `script.xml.state` files to the directory where you ran the `beast` command (notably, not to the directory where your scripts are!). Then, if you need to rerun an analysis, simply run ``` /path/to/beast/bin/beast -resume scripts/script.xml ``` And that's all! One thing to point out is that BEAST2 will then run this analysis for as long as your `chainLength` (`n_gens` in our script-building scripts) argument is, so if it is *e.g.* 1 billion and you resume a finished run, you will end up with 2 billion generations. Make sure to change that argument if you'd like a different number of generations! Once your analyses are done running (they took 2-4 days in my cluster, but that might vary), we then need to test them for convergence, and combine them into one aggregate posterior sample. Optionally, you might also want to obtain a summary tree for your analysis. Let's go through the commands for each of these steps below. First, let's test convergence. Most researchers would use the Tracer software for this, and BEAST2 has [a great tutorial](https://beast.community/analysing_beast_output) for doing just that. I recommend you check your output with Tracer, but here I will present an alternative way to check convergence using the R package `coda`. We will read each of our log files into R, use `coda` to check their effective sample size (ESS) with `effectiveSize`, and ensure we have a good effective sample size for each of them. We will apply a 50% burnin, but feel free to check how things change by changing the `burnin` argument below. ```{r} # burnin percentage burnin <- 0.5 # number of columns in your log (excluding sample column) n_cols <- 23 # make sure to change this if you are running this for your # own analysis and have a different number of parameters # data frame to hold our effective sample sizes ess_df <- data.frame(matrix(nrow = n_scripts, ncol = n_cols)) # iterate through our scripts for (i in 1:n_scripts) { # read this log log <- read.delim(paste0(out_dir, "srfbd_first_", i, ".log"), sep = "\t", header = TRUE, comment.char = "#") # the comment.char argument is needed because BEAST2 # writes the entire script to the top of the log file, # but we can ignore that with comment.char # we need to remove the first column, since that's just the generation marker log <- log[, -1] # then we need to apply some burnin log <- log[(0.5 * nrow(log) + 1):nrow(log), ] # this will leave us with 500 samples per log # the +1 is required since BEAST2 records the initial state # finally, we can use coda to check the effective sample size ess <- coda::effectiveSize(log) # add to our data frame ess_df[i, ] <- ess } # name ess_df columns colnames(ess_df) <- colnames(log) # check the minimum unlist(sapply(1:ncol(ess_df), function(c) min(ess_df[, c]))) ``` For my analyses, the lowest ESS was ~171, which is pretty good. `coda` uses a bit of a stricter calculation for ESS than Tracer, so do not be surprised if you see higher values in that software. Since we have achieved convergence in each of our runs, we can then use the BEAST2 companion program LogCombiner to aggregate our posterior samples into one. ``` /path/to/beast/bin/logcombiner -b 50 \ -log output/srfbd_first_1.log \ -log output/srfbd_first_2.log \ -log output/srfbd_first_3.log \ -log output/srfbd_first_4.log \ -o output/srfbd_first.log /path/to/beast/bin/logcombiner -b 50 \ -log output/srfbd_first_1.trees \ -log output/srfbd_first_2.trees \ -log output/srfbd_first_3.trees \ -log output/srfbd_first_4.trees \ -o output/srfbd_first.trees ``` You may then do your due diligence and check that the `srfbd_first.log` file also shows we have converged. This is necessary because even if all four of our separate scripts have converged, they might have converged to different parameter values. Checking this final file for convergence would of course be a straightforward exercise of repeating your `coda` or Tracer checks above, so I will leave that to you. Now that we have our final log and tree files, each with around 2000 samples, we can proceed to analyze our results. First, however, you might want to generate a tree summary. While a thorough examination of your full posterior sample is of course necessary for any Bayesian analysis, it is often difficult to avoid the generation of a tree summary. You might need one tree to run some comparative methods on, or simply would like to have a representative tree to add to your paper/talk. Since SRFBD generates budding phylogenetic trees, building tree summaries is also something we need new tools for. The `sRanges` package already contains an implementation of a maximum clade-credibility (MCC) tree algorithm. Let's build our tree and see how it looks! Note that we will need the `SRTreeAnnotator` tool for this, which requires `applauncher` (accessible in BEAUti through `File > Launch apps`, if you'd like a GUI). ``` /path/to/beast/bin/applauncher SRTreeAnnotator -burnin 0 \ -trees output/srfbd_first.trees \ -out output/srfbd_first_mcc.nex ``` While `paleobuddy` does include functions to plot a budding phylogeny, the R plotting window is not ideal for visualizing phylogenies with more than a few dozen tips. Luckily, [IcyTree](https://icytree.org/) is a very powerful browser-based tool for visualizing trees, and it already allows for the visualization of budding phylogenies. Simply select the `srfbd_first_mcc.nex` file, then click `Style > Tree layout > Transmission tree`. You can visualize the stratigraphic ranges of each species by selecting `Style > Colour edges by > range`, and mark sampled ancestors (fossil samples that left sampled descendants, *i.e.* fossils that are not tips) by pressing `m`. Feel free to play around with other style options--IcyTree is a great tool for generating publication-level images of phylogenies, even budding ones!! Let's see how our tree turned out. 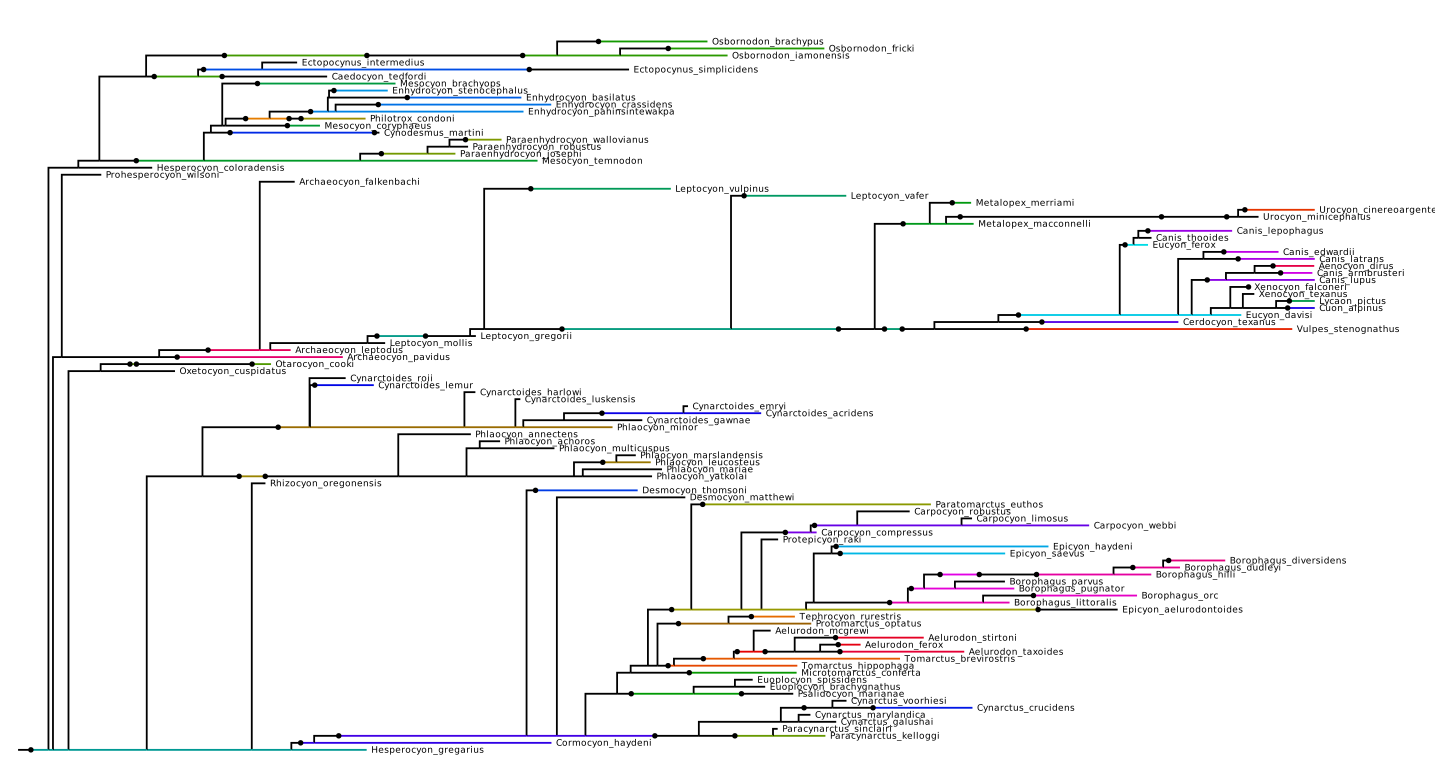 I made the font for the species names reasonably small because they start overlapping each other, but you can zoom in on your own tree to explore the topology in more detail. Note that by default the tips will be called `genus_species_last` or `genus_species_first`, since they represent a first/last occurrence rather than a species. If you'd like to label them by species, select `Style > Tip text > taxon`. One thing to note about the trees we get as output from SRFBD is that besides being budding trees, they also maintain the taxonomic continuum implied by stratigraphic ranges. That means any tree that would break an SR (*i.e.* placing the `genus_species_first` and `genus_species_last` in separate branches of the tree) would not be accepted by the model, so you can be sure that every SR tree (as we have come to call these) will have the SR of a species as one unbroken segment within a branch. We will discuss the MCC tree further in our results below, so keep it in your back pocket! In case you haven't had time to run the full analysis yet but want to run our results, you can download the result files from my analysis: [Log file](/files/tutorials/srfbd/results/srfbd_first.log){: .btn .btn--primary download="srfbd_first.log"} [Tree file (compressed)](/files/tutorials/srfbd/results/srfbd_first.trees.zip){: .btn .btn--primary download="srfbd_first.trees.zip"} [MCC tree](/files/tutorials/srfbd/results/srfbd_first_mcc.nex){: .btn .btn--primary download="srfbd_first_mcc.nex"} ## Results ### Parameter estimates To start, we can take a look at the diversification and fossil sampling rate estimates from our model. While this is a constant-rate model, and therefore not incredibly realistic (keep an eye on [Kate Truman](https://scholar.google.com/citations?user=cNMpBL0AAAAJ&hl=en) from the Gavryushkina lab for a paper on the skyline SRFBD model coming out soon!), this is still a worthy exercise. ```{r} # read the full log log <- read.delim(paste0(out_dir, "srfbd_first.log"), sep = "\t", header = TRUE, comment.char = "#")[, -1] # let's check the histograms for our rates and origin par(mfrow = c(2, 2)) # sampling proportion hist(log$samplingProportionFBD, main = "Posterior sample of sampling proportion", xlab = "diversification (proportion of species)", probability = TRUE) abline(v = mean(log$samplingProportionFBD), col = "#DF536B", lwd = 2) curve(dbeta(x, 3.1, 6.9), add = TRUE, col = "#2297E6", lwd = 2) # let's look at the 95% credible interval for this one quantile(log$samplingProportionFBD, c(0.025, 0.975)) # diversification rate hist(log$diversificationRateFBD, main = "Posterior sample of diversification rate", xlab = "diversification (events/lineage/my)", probability = TRUE) abline(v = mean(log$diversificationRateFBD), col = "#DF536B", lwd = 2) curve(dexp(x, 1 / 0.0767), add = TRUE, col = "#2297E6", lwd = 2) # turnover hist(log$turnoverFBD, main = "Posterior sample of turnover", xlab = "turnover", probability = TRUE) abline(v = mean(log$turnoverFBD), col = "#DF536B", lwd = 2) curve(dbeta(x, 2, 1), add = TRUE, col = "#2297E6", lwd = 2) # origin hist(log$originFBD, main = "Posterior sample of the origin", xlab = "origin (mya)", probability = TRUE) abline(v = mean(log$originFBD), col = "#DF536B", lwd = 2) curve(dexp(x - 37, 1 / 9.67), add = TRUE, col = "#2297E6", lwd = 2) ``` To better visualize things, I added a red line marking the posterior mean, and a blue line showing the prior distribution. You can see that for every parameter we've checked, the posterior sample is pretty different from the prior, which is a good sign! It is an indication that our results are coming from the data, as opposed to just returning the prior (which might happen when your data are not very informative). What we see for diversification and turnover is pretty standard: low diversification, turnover very close to 1. This is why skyline models are useful--if we are just trying to fit one rate to an entire tree, we end up on an average that just relates to the general trend of going from one species to a few in ~40 million years. For example, the maximum likelihood estimate for diversification rate for a tree with 5 extant species that started at time $T$ with one species is $ln(5) / T$. If we took $T = 38$ that's around $0.04$, which is pretty close to our posterior sample. Still, it is good to see that the results make sense. For our sampling proportion, we see a mean of $0.65$, with a 95% credible interval of $\{0.59, 0.71\}$. This indicates an estimate of 178-215 total extinct canid species. By my estimations there are 206 described extinct canids, and while this number will change with which expert you consult (and, more importantly, there is an unknown number of undescribed ones), the model estimates seem reasonable. Finally, let's talk about the origin. Our prior distribution (an exponential with an offset of $37$mya and rate of $9.67$) was chosen because it has a minimum around the oldest possible fossil occurrence in our dataset, 95% of the density below 66mya (around the K-Pg boundary), and a mean of around $47$mya, which is the age of some basal caniforms. Our posterior sample seems to indicate a lot of confidence that the origin is on the lower range of that, closer to $37$mya. While the rates estimated by SRFBD are easy to interpret, it is occasionally useful to reparameterize the rates to speciation, extinction, and fossil sampling. ```{r} # do the transformations backwards lambda <- log$diversificationRateFBD / (1 - log$turnoverFBD) mu <- lambda * log$turnoverFBD psi <- log$samplingProportionFBD * mu / (1 - log$samplingProportionFBD) # plot the histograms par(mfrow = c(3, 1)) hist(lambda, main = "Posterior sample of speciation rate", xlab = "speciation rate (events/lineage/my)", probability = TRUE) hist(mu, main = "Posterior sample of extinction rate", xlab = "extinction rate (events/lineage/my)", probability = TRUE) hist(psi, main = "Posterior sample of fossil sampling rate", xlab = "fossil sampling rate (events/lineage/my)", probability = TRUE) ``` It seems like we would expect, on average, a speciation event every ~3my, an extinction event every ~4my, and a sampling event every ~2my, per living lineage. Again, not much of interest to explore without skyline rates, but just an illustration of what we could explore with rate estimates. One last interesting parameter to explore here is the sampled ancestor counts. Sampled ancestors represent hidden speciation events, *i.e.* when a species might have generated a different species **after** the time of its last fossil sample. They might also be the signature of anagenesis, and it might be impossible to distinguish between these two possibilities. Either way, the number of species estimated to be sampled ancestors may be of interest. ```{r} # histogram of the number of sampled ancestors hist(log$SACountFBD, main = "Posterior sample of sampled ancestor count", xlab = "Number of sampled ancestor species") ``` It seems like we have a median of around 17 species being sampled ancestors, which is reasonably low (14%). In my tests of SRFBD and traditional FBD (in prep), I've found that SRFBD is generally more conservative in setting species as sampled ancestors, which leads it on average to miss some SAs, but have a reasonable degree of confidence in the species it does assign as SAs being SAs. We will keep this in mind in our discussion of topology below. We could also spend some time looking at our morphological evolution parameter estimates, but will skip that to avoid making a long tutorial even longer. In a future tutorial I mean to explore how the choice of where to place our data (first occurence or both first and last occurrence) may change our results. ### Phylogeny To explore our topology estimates, we will use the `paleobuddy` package. `paleobuddy` implements a number of useful functions for exploring the topology of a budding phylogenetic tree, mostly inspired by functions in the `ape` package. We will use our [MCC tree](#mcc) as a guide for interesting nodes in the topology, and then check how that result is represented within our posterior sample of trees. I recommend having the MCC tree open in an IcyTree browser window as we go through this section, since I had to shrink the font of the species names in the image above so much. To work with these trees in R, we will be translating them into `buddPhylo` objects, which `paleobuddy` implements. Let me pause and speak a bit about `buddPhylo`. A `buddPhylo` is a data frame with each row representing a branch of a budding phylogeny, with information on each node's parent, orientation (descendant/ancestor), etc. In BEAST2 trees (and therefore the `buddPhylo` objects we are working with), the tips are named as `genus_species_first` or `genus_species_last`, depending on whether they represent the first or last occurrence of a given species. Therefore, the `name` column here will include that first/last tag, and the `taxon` column for each of those rows will be set to the species itself (so in this example, `genus_species`). Nodes that don't represent taxa (*i.e.* internal nodes) will simply be named as numbers, and hava `NA` in the `taxon` field. Now, let's read our tree sample. We will use `paleobuddy`'s `read.nexus.buddPhylo` function, which reads each tree in the file, and saves them as a list of `buddPhylo` objects. ```{r} # read 2000 budding phylogenies--it takes a little bit of time trees <- read.nexus.buddPhylo(paste0(out_dir, "srfbd_first.trees")) # plot our starting tree, without tip labels so as to not crowd the plot plot(trees[[1]], show.tip.label = FALSE) # read our mcc tree mcc_tree <- read.nexus.buddPhylo(paste0(out_dir, "srfbd_first_mcc.nex")) ``` You can get some quick details about a `buddPhylo` object with the `print` function. ```{r} # how many speciation events, how many SAs, and the first # few species, with the species that generated them print(mcc_tree) ``` Now let's investigate some interesting aspects of our MCC tree, and use paleobuddy to write functions to explore that. First, consider the grey wolf (*Canis lupus*). I'm sure that's a lot of reader's favorite dog. Because this tree explores morphology only, we see the dire wolf species complex (*Aenocyon dirus* and *Canis (Aenocyon) armbrusteri*) being recovered very close to *lupus* (see @perri2021dirus and @gedman2025dirus for an idea of what happens when we add dire wolf DNA into the mix). How often does this configuration (*dirus*-*armbrusteri* descending from within the *lupus* range) show up in our posterior sample of trees? We will write a custom function, using a number of `paleobuddy` functions: - `is.monophyletic.buddPhylo` takes a `buddPhylo` and a list of tips (including the `first` or `last` tags), and returns a logical on whether that list of tips is monophyletic in the tree. - `getMRCA.buddPhylo` takes the same arguments, and returns the `name` field of the node that represents the most recent common ancestor (MRCA) of the tips in question. - `getDescendants.buddPhylo` takes a `buddPhylo` and node `name`, and returns all tips that descend from that node. - `getChildren.buddPhylo` takes the same arguments, and returns only the immediate children of the node in question. If the node is a speciation node, the children are names `ancestor` and `descendant` to identify the orientation. If it is a sampled ancestor node, the children are named `sampAnc` and `lineage`. And if it is a tip, the return is `NULL`. ```{r} # function to check how often a clade is descended # from within a species's range direct_descendant <- function(trees, clade, species, lineage = FALSE) { sum(unlist(lapply(trees, function(x) { # check if clade is monophyletic, if not then this is already not true if (!is.monophyletic.buddPhylo(x, clade, excludeSampAnc = FALSE)) return(FALSE) # get the full clade (clade + last occurrence of species) full_clade <- sort(c(clade, paste0(species, "_last"))) # if we want to check if the *lineage* of that species generated the # clade, we also allow for the budding to be not from within the range if (lineage) full_clade <- sort(c(full_clade, paste0(species, "_first"))) # get the node that is the MRCA of clade+last occurrence of species mrca <- getMRCA.buddPhylo(x, full_clade) # find the descendants of this mrca desc <- sort(getDescendants.buddPhylo(x, mrca)) # and check if this is exactly equal # to the clade+last occurrence of species res <- identical(desc, full_clade) # if lineage is true, we also need to check that clade is # the descendant child (if not, it must be since it's within the range) if (lineage) { # get the MRCA of just the clade mrca_clade <- getMRCA.buddPhylo(x, clade) # check that this is the "descendant" member of the children of the MRCA res <- res && mrca_clade == getChildren.buddPhylo(x, mrca)[2] } # return return(res) }))) / length(trees) } ``` This function then checks, for each tree, whether the `clade` is monophyletic, and whether the clade is budding off of directly from the range of `species`. Optionally (using the `lineage` argument) we can check whether the clade buds off the **lineage** leading to the range of that species, instead of within the range itself. These are two distinct, but similar, biological scenarios. Let's check what the case is for the *lupus*-*armbrusteri*-*dirus* complex. ```{r} # define the clade clade <- c("Aenocyon_dirus_first", "Aenocyon_dirus_last", "Canis_armbrusteri_first", "Canis_armbrusteri_last") # and species species <- "Canis_lupus" print(paste0("Proportion of trees where clade buds off of species's range: ", direct_descendant(trees, clade, species))) print(paste0("Proportion of trees where clade buds off of species's lineage: ", direct_descendant(trees, clade, species, TRUE))) ``` If you check the node comments of the speciation node in question in our MCC tree (hover the mouse over the branch leading to that node), you will likely see a value that is the sum of those two for the posterior probability of that clade (for my tree, it is `posterior = 0.41`). That's because that posterior calculation considers both of these configurations. This is a reasonably low posterior probability, which likely indicates that the data are not extremely uncertain. We can also ask questions about the higher level topology. For example, the ancient canid *Hesperocyon gregarius* appears as the oldest species in our MCC tree. All other lineages are budding off of its range. This matches the expert consensus, which is that *Hesperocyon*, a member of the Hesperocyoninae subfamily, generated the other canid subfamilies, Borophaginae and Caninae. We can check how often this happens in our tree sample fairly easily. ```{r} # vector to hold all tips all_tips <- unique(mcc_tree$lineage) all_tips <- all_tips[!is.na(all_tips)] # minor modifications to remove each occurrence of gregarius from all_tips all_but_hg1 <- all_tips[all_tips != "Hesperocyon_gregarius_first"] all_but_hg <- all_but_hg1[all_but_hg1 != "Hesperocyon_gregarius_last"] # function to check which percentage of our tree # sample has certain clade as monophyletic prop_monophyletic <- function(trees, clade) { sum(unlist(lapply(trees, function(x) is.monophyletic.buddPhylo(x, clade, excludeSampAnc = FALSE)))) / length(trees) } # let's check it for those two clades print(paste0("Proportion of trees where all but H_gregarius_first is monophyletic: ", prop_monophyletic(trees, all_but_hg1))) print(paste0("Proportion of trees where all but H_gregarius is monophyletic: ", prop_monophyletic(trees, all_but_hg))) ``` For my tree sample, the first value was around `0.41`, and the second `0.01`. One important thing to note here is that SR trees always have the stratigraphic range of a species unbroken. Because of that, for every tree in our sample with the clade excluding `hesperocyon_gregarius_first` as monophyletic, there are only two possible configurations they could take: - The entire *Hesperocyon gregarius* SR is a sampled ancestor to the rest of Canidae. This would mean that the clade excluding both *gregarius* occurrences would be monophyletic, which as we saw happens in 1% of our trees. - All other canid lineages bud off the range of *gregarius*, as we see in the MCC tree. Because this is the only other option, we can infer that it happens in around 40% of trees in our sample. Our results therefore weakly support the expert consensus, *i.e.* *H. gregarius* having generated the rest of Canidae, another reminder that these data might not be enough to make strong assertions. You can investigate further what might be the first diverging lineage (*e.g.* try doing the same procedure as above but with `Prohesperocyon_wilsoni_first` as the excluded tip), and you will find that this is the most likely configuration, even with such a low posterior probability. Still, this is a great example to illustrate the power of SR trees: how easy was it to test such a fundamental hypothesis about the evolutionary history of Canidae? We could also of course check divergence-time estimates for clades we are interested in. Since budding trees don't have that much extra to say about divergence times, I will just give one quick example so we can check how to extract this information from `buddPhylo` objects. Let's check the distribution of the time at which the first diverging Canidae lineage buds off the range of *Hesperocyon gregarius*, in the 40% of trees where that happens. ```{r} # extract the divergence times div_times <- unlist(lapply(trees, function(x) { # check if all_but_hg1 is monophyletic--if not we don't want this tree if (is.monophyletic.buddPhylo(x, all_but_hg1, excludeSampAnc = FALSE)) { # get the time return(node.time.buddPhylo(x, getMRCA.buddPhylo(x, all_but_hg1))) } else { return(NA) } })) # plot it hist(div_times, main = "Divergence time distribution for Canidae\\H_gregarius_first", xlab = "Time (mya)") ``` We quickly checked the time of the node representing the MRCA of the clade excluding `hesperocyon_gregarius_first` with the `node.time.buddPhylo` function. It seems like most of these trees have that first diverging clade budding off the range of *gregarius* within a pretty tight 2my interval. It would take a little more defining variables, but we could repeat this analysis to *e.g.* plot the divergence time between the grey wolf (*Canis lupus*) and the coyote (*Canis latrans*), which might give you some information about the timing of the reintroduction of wolf-like canids to North America. Because of the extra information in SR trees, you could even check specifically whether the distribution of divergence times of a clade change when the clade switches orientation. World's your oyster! A more detailed analysis of the topology and divergence times of our posterior sample would of course require a much more involved exploration of all the clades in each of the trees, their orientations/sampled ancestor MRCA, and their relative frequencies. Maybe in the future I will write a move involved tutorial about this, but for now I will just mention another `paleobuddy` function that can aid in that task. ```{r} clades <- extract.clades(mcc_tree, considerSAs = TRUE, considerOrientation = TRUE) # this generates a total of 197 clades, i.e. length(all_tips) - 1 # check a few clades to understand the formatting clades[[100]] clades[[140]] ``` By default, `extract.clades` just returns a (sorted) list of strings laying out the clades implied by the tree in the first argument, with tip names separated by commas. You can use the two arguments `considerSAs` and `considerOrientation` to get more information on each of these clades. If the former is true, each clade defined by a sampled ancestor node will have the name of the SA species after the `\001SA:` tag. If the latter is true, each clade defined by a speciation node will have the subset of tips that represent the ancestor side of the budding speciation after the `\001ANC:` tag. You can therefore use this function to easily list clades contained in each tree, including their orientation and sampled ancestors, to aggregate information about the clades supported in your posterior sample. #### Exercise Try setting `attach <- "both"` when building the scripts, and repeating the rest of the tutorial. Do our topological results change significantly?
## Conclusion In this tutorial, we worked on writing scripts to run SRFBD analyses in BEAST2, and processing the results with paleobuddy. We covered how to write the BEAST2 scripts using my custom R scripts, the basics of assessing convergence for your analyses, and some simple ways to analyze the resulting estimates for parameter values and tree topology. The stratigraphic-range fossilized birth-death model is a very exciting and powerful model, but it is also highly technical and difficult to use because of the `xml` setup. I hope I've provided you with enough information to apply the model to your own data, and I'm planning to expand this tutorial in the future to help further. Please feel free to contact me if anything was confusing, if I can further help you get an analysis working, or if you have any tips on making this tutorial better. Thank you for reading! ## References